

Max Dubinin, Tech Lead & Shai Cantor, Software Architect
Komodor’s Agentic Operations Platform enables organizations to build custom agents under shared governance and context, and orchestrate them in end-to-end workflows for AI SRE, AI Software Operations, and Cost Optimization. With Komodor you can confidently implement autonomous operations in mission-critical environments – fully governed from the first run.
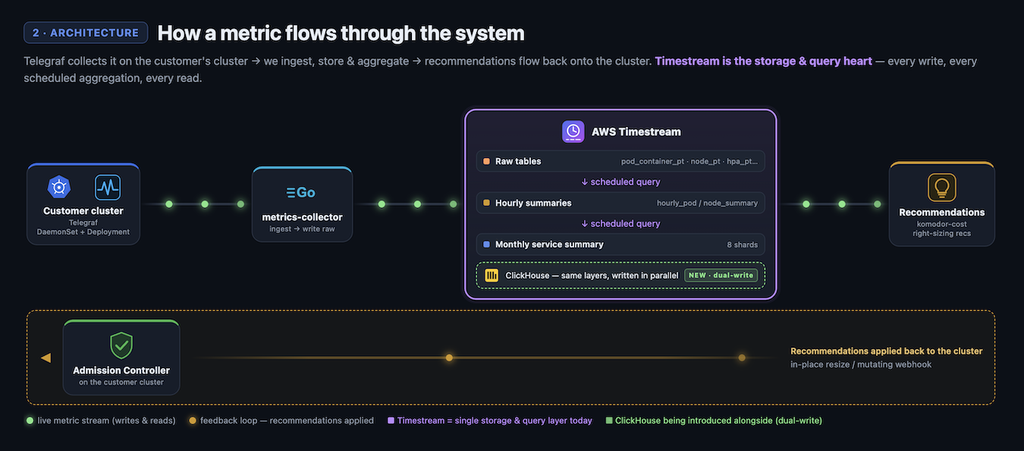
To accomplish this, every CPU, memory, and GPU sample from every customer workload Komodor watches lands in a single time-series store. It feeds four different product surfaces and our Agentic AI backbone. Until this year, that store was Amazon Timestream. Then AWS quietly ended it.
On June 20, 2025, AWS closed new-customer access to Amazon Timestream for LiveAnalytics — the edition our metrics platform was built on — and pointed new customers toward a different engine entirely. Reading between the lines: “we continue to invest in security, availability, and performance” is EOL language. No new features, closed access, a different recommended path. We weren’t going to build our future on a product AWS had stopped building a future for.
That announcement, combined with a cost line we’d been watching for a while, kicked off an eight-month project: replace the storage and query layer under Komodor’s entire cost and reliability product surface, migrate roughly 5.9 billion rows of ingest a day, and do it without a single customer noticing.
This is the story of our Timestream to ClickHouse migration.
What Timestream did for us
Amazon Timestream for LiveAnalytics is AWS’s fully managed, serverless time-series database — auto-tiered, with a hot in-memory store for recent data and a cheap magnetic store for history, aging data between them by a per-table retention policy. It has a SQL-like query language with time functions (BIN, ago(), APPROX_PERCENTILE), and scheduled queries that roll raw data up into hourly and daily aggregates inside the database. It’s serverless and billed on data written, data stored per tier, and query compute in TCU-hours (Timestream Compute Units).
At our scale, that meant:
- ~5.9B rows/day ingested
- ~68K records/second, peaking around 85K/s
- 4.04 TB in the magnetic (long-term) store
Every CPU/memory/GPU sample from every customer workload lands in Timestream’s raw tables. Scheduled queries summarize them hourly and monthly. Every Cost, Right-Sizing, and Reliability screen in the product — plus the resource metrics agent tool, which pulls CPU/memory usage (avg/p90/p95/p99/max over 24h, 1h, and 10m windows) for root-cause analysis — reads back from those tables.
Why we had to leave
The AWS deprecation notice was the initial trigger, but it wasn’t the only reason, and arguably not even the biggest one.
Cost. Timestream’s TCU-hour pricing was unpredictable and was our single biggest data cost, running ~$38K/month.
No DML. We couldn’t delete or update rows, or deprecate columns ad hoc — a real constraint for a product that’s constantly evolving its own metrics schema.
No metadata joins. There was no way to join static RDBMS data (like node pricing) against the time-series data, which meant workarounds everywhere we needed to combine the two.
Scheduled-query limits. We regularly hit AWS’s memory-processing ceilings on scheduled queries, which caused aggregation failures.
No local or lab environment. Timestream can’t run locally, so there was no way to write real tests against ingest and queries — everything had to be validated against the live service.
No visibility into query performance. There was no way to run an EXPLAIN or otherwise see what a query was actually doing inside the engine. When something was slow or delayed, the only recourse was an AWS support ticket — and a slow support cycle while customers were affected was a familiar, painful loop.
The AWS EOL notice made this a “solve it now” problem instead of a “someday” problem — and customers had already felt this pain directly, through slow, hard-to-debug queries during live incidents.
Why ClickHouse won the Timestream migration bake-off
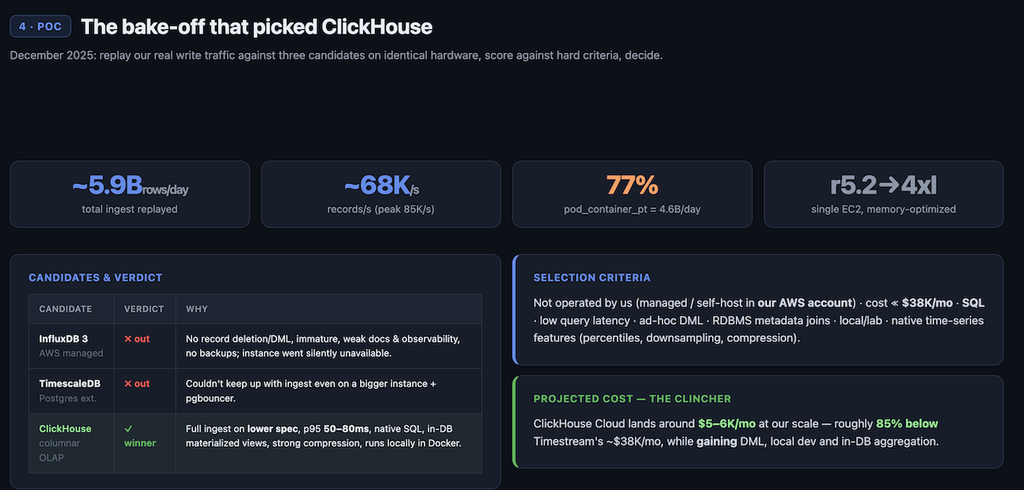
In December 2025, we replayed our actual production write traffic — the full ~5.9B rows/day, ~68K/s (peak 85K/s) — against three candidates on identical hardware (a single memory-optimized EC2 instance, moved from an r5.2xlarge up to an r5.4xlarge during the test).
The selection criteria were concrete: not operated by us (managed, or self-hosted inside our own AWS account), cost far below the ~$38K/month baseline, real SQL, low query latency, ad-hoc DML support, the ability to join RDBMS metadata, a local/lab environment, and native time-series features (percentiles, downsampling, compression).
| Candidate | Verdict | Why |
|---|---|---|
| InfluxDB 3 (AWS managed) | Out | No record deletion/DML, immature, weak docs and observability, no backups — the instance went silently unavailable during testing. |
| TimescaleDB (Postgres extension) | Out | Couldn’t keep up with our ingest rate even on a bigger instance with pgbouncer in front of it. We know Postgres well and might have made it work with enough engineering effort, but the ongoing maintenance overhead would have been substantial. |
| ClickHouse (columnar OLAP) | Winner | Handled full ingest on a lower spec than the other two, p95 query latency of 50–80ms, native SQL, in-database materialized views, strong compression, and it runs locally in Docker. |
The clincher was cost: ClickHouse Cloud, at our scale, projected to roughly ~$5–6K/month — about 85% below Timestream’s ~$38K/month — while gaining ad-hoc DML, local development, and in-database aggregation instead of losing them.
The pointed irony: InfluxDB 3 is essentially the engine AWS itself recommends today as the replacement path for Timestream customers. We tested it anyway, on the theory that AWS’s own recommended successor deserved a fair shot — and it was the first one out, on immaturity and observability grounds. That reinforced the decision to leave the AWS ecosystem for this workload entirely rather than move sideways within it.
Why managed ClickHouse Cloud, not self-hosted
The obvious follow-up question — raised directly by the team during the internal review of this project — was why not self-host ClickHouse and capture even more of the savings. The answer was operational, not financial: a self-hosted, stateful time-series database means owning its availability 24/7. If a node crashes at 2:17 a.m., the database goes down until an engineer manually scales, repairs, or fails the cluster over. A managed service’s premium buys back that on-call burden.
ClickHouse Cloud landed as the middle ground: not the AWS-managed black box Timestream was, where queries could quietly fail or lag with no way to see why, but not fully self-owned infrastructure either. It came with out-of-the-box Datadog integration, and — a smaller but real factor — a ClickHouse solutions architect based nearby whom the team could actually sync with directly, something Timestream never offered.
Designing a migration nobody would notice
We chose to avoid a high-risk weekend launch. We wanted every table and every query to move through the same four stages, each one gated by a feature flag — per table, per query-group, per account — so any stage could be reverted instantly, with no deployment needed. The main idea of these four stages was to control which engine is queried and which engine is served as the authoritative result:
- Dual-write — write to both engines. ClickHouse starts accumulating the 30 days of history the monthly aggregation needs.
- Dual-query / shadow — run the query against both engines, compare the results, but keep serving from Timestream.
- Cut over — flip to serving from ClickHouse, per account. Timestream keeps ingesting the whole time as a safety net.
- Decommission — once a stable parallel run has held, stop writing to Timestream, drop its templates, and delete it.
Under the hood, one query executor contains both a Timestream template and a ClickHouse template for every query; the query-mode flag picks which engine(s) run at request time. Post-migration, “we remove the Timestream template from that definition, and the executor short-circuits straight to ClickHouse with zero flag-evaluation overhead”.
The result: rollback at any stage is a single flag flip, not a deploy. And because Timestream keeps ingesting live data until the very last step, a bad cutover is invisible to customers — it just gets flipped back.
The plan, bottom-up
We sequenced the build bottom-up, because the hardest constraint was time, not code:
- Foundation — shared Go/Python ClickHouse packages, a migration mechanism, the dual-query layer, ClickHouse testcontainers for the test suites.
- Raw dual-write — 7 raw tables, started first.
- Hourly aggregations — implemented as ClickHouse refreshable materialized views.
- Daily/monthly aggregations — the same approach, refreshable materialized views (service summary cron jobs, 8 shards).
- Read migration — roughly 35 queries in multiple services.
- Validation — the parity comparator and cost-parity report.
- Cutover — per-account, tiered rollout.
- Decommission Timestream.
Both aggregation layers run as ClickHouse refreshable materialized views, keeping the summary tables continuously up to date without any custom scheduling logic of our own — mirroring what Timestream’s scheduled queries had done, but as a native, engine-managed mechanism.
Monthly aggregation needs 30 days of history to mean anything, so raw dual-write had to start on day one — every day of delay to that step pushed the entire timeline out by the same amount. It was the critical path for everything downstream.
Bottom-up ordering also meant each layer was validated before the next layer read from it, and Timestream kept serving production traffic until a query was explicitly flipped over — so a mistake at any single phase was a flag flip away from rollback, never a customer-visible outage.
Trusting AI-written SQL enough to serve customers with it
Claude wrote most of the ClickHouse SQL for this migration — research, planning, and validation were all heavily AI-assisted. An additional confidence layer and a major force multiplier were ClickHouse Agent Skills and ClickHouse docs MCP – which are tools maintained by ClickHouse themselves for LLM assistant development, troubleshooting, review and information. Grounding the model in the engine’s own documented behavior, rather than a plausible-sounding guess, made a real difference — but that’s exactly why nothing shipped on trust alone either way. Every generated query had to pass four independent gates before it could serve a single customer request:
- Unit tests — SQL template builders, parameter extraction, argument binding: pure-logic checks on every query definition.
- Component tests — real queries run against a live ClickHouse testcontainer, spun up per test suite and seeded with data, asserted end-to-end. Adding ClickHouse testcontainers to both the Go and Python suites meant tests exercised actual SQL against a real ClickHouse instance instead of mocks — catching dialect, type, and aggregation bugs that mocks would have hidden.
- Parity tests — the same inputs run against Timestream and ClickHouse, with results compared field-by-field, against both synthetic and real data.
- Production shadow — the dual-query comparator runs both engines against live traffic and logs every single comparison to Datadog, for example:
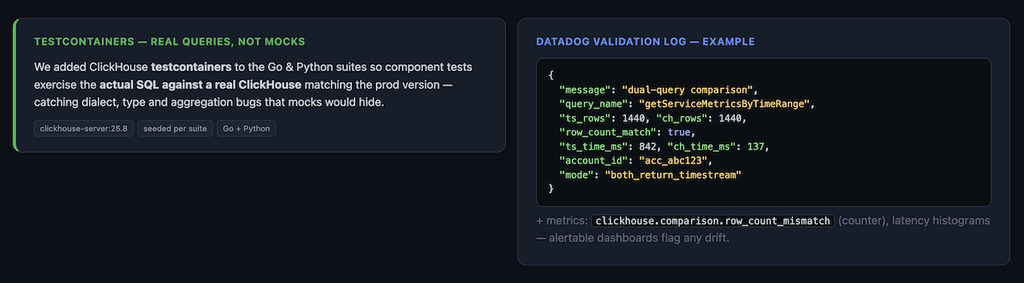
Everything was backed by alertable Datadog metrics and latency histograms, so any drift between the two engines surfaces immediately instead of silently accumulating.
“If we didn’t leverage AI workflows to generate those custom validation reports, comparing live customer metrics across dual engines down to the single integer would have taken our team weeks of manual data mapping. We simply wouldn’t have had the bandwidth to achieve this level of data confidence.” — Max
Two reports that made the migration provable, not just plausible
Passing tests proves a query works. It doesn’t prove the migration works — that every number a customer sees on ClickHouse means the same thing it meant on Timestream. We built two purpose-made reports to close that gap.
The cost-parity report
Mirrors the real product pages — Cost Overview, Allocation, Right-Sizing, Pod-Placement — so any engineer or PM can eyeball Timestream vs. ClickHouse exactly the way a customer would see it: side by side, with a Δ% on every metric and card, color-coded with per-account drill-downs across all accounts, sorted worst-first, plus latency comparisons and root cause tags linking red discrepancies straight to their investigation.
The data lineage report
Built by Max, this is a second and different kind of validation: instead of comparing values, it maps the wiring — every raw table, through every hourly/daily/monthly aggregation, to all 85 read queries that depend on it, down to the column level. Pick any output column and see exactly which upstream tables and columns feed it. It surfaces what triggers each query (an endpoint, a cron, an SQS message), and it catches orphaned or missing dependencies before they ever reach a cutover. Value-parity can tell you if two numbers match; lineage tells you where each piece of data actually originates from — confirming a ClickHouse query is reading from the sources it’s supposed to, not just that its output happens to look right.
What we were afraid of, and what actually broke
Here’s the one nobody predicted. Both engines were ingesting the exact same raw data stream and running the exact same analytical queries — so when the parity numbers didn’t match, the instinct was to assume a bug in the new pipeline. It took weeks of tracing individual data points to find the real cause, and it wasn’t in ClickHouse at all.
The root cause traced back to our own hand-rolled Telegraf plugin — not Telegraf itself, but the custom collection logic we built on top of it to harvest metrics on customer clusters — which occasionally emits duplicate or partial payloads for the same metric block. Timestream and ClickHouse just handle that duplicate differently:
- ClickHouse replacingMergeTree keeps the latest chronological record for a given key and discards the older one. (This isn’t actually fixed behavior — ClickHouse supports a version column that lets you explicitly declare which row for a given key is authoritative. That wasn’t a viable option here, given how our metrics-collector writes across a distributed pipeline.)
- Timestream does the opposite: it locks in the first record it receives for a timestamp and silently drops every duplicate that arrives after it.
That’s also why the validation bar was set so high. A customer opening a cost dashboard and seeing a savings figure change on refresh doesn’t read that as “we fixed an old bug” — it reads as “this tool can’t be trusted.” The team was validating deltas that, on the largest enterprise accounts, represented differences in the hundreds of thousands of dollars in tracked cloud spend, and tens of thousands on more typical accounts. That’s the real reason the cost-parity and lineage reports exist — this needed to be provably right, not just directionally close, before a single customer saw a ClickHouse-backed number.
What we can say for certain about the rest: every stage took longer than planned, for reasons that are themselves useful data for the next team attempting something like this.
- Read migration ran ~2 weeks over. Porting the SQL itself was quick. Parity was the tax: dozens of field-name and parser bugs only surfaced in production after flag flips, forcing a full three-layer restructure of roughly 33 endpoints, on top of competing priorities.
- Validation and parity ran ~3 weeks over. Real divergences — around deduplication, enrichment, and percentile calculations — forced repeated multi-day 30-day backfills, and even a few raw-table redesigns that took days to land.
- Rollout ran ~3 weeks over. Sensitive customers got postponed and migrated one at a time; some hard discrepancies were only fixable by letting 30 days of fresh data accumulate.
All told, that’s roughly eight weeks of slip against the original estimate. Going in, the team expected this to take less than a quarter. It took from December 2025 to July 2026 — about seven months.
The results
Every reason we left Timestream is now a line item in what we gained.
| Pain (why we left) | Where we landed |
|---|---|
| Cost — ~$38K/month, unpredictable TCU pricing | ~$5–6K/month — ~85% lower, and predictable |
| Vendor — EOL AWS product, no future investment | Actively developed, widely adopted engine; we own our roadmap |
| Mutability — no delete/update/column changes | Ad-hoc DML and schema evolution |
| Metadata joins — no way to join static RDBMS data | Join RDBMS metadata directly in queries |
| Aggregations — scheduled queries hit AWS memory ceilings | Run without ceilings, via INSERT…SELECT jobs and crons |
| Dev & testing — no local/lab environment | Runs in Docker, with real component and parity tests |
And queries got dramatically faster in the process. Measured across 10.3 million production dual-query comparisons over 14 days:
| Percentile | Timestream | ClickHouse | Improvement |
|---|---|---|---|
| Average | 906ms | 33ms | ~27x |
| Median | 187ms | 7ms | ~27x |
| p75 | 257ms | 12ms | ~21x |
| p95 (tail) | 1,274ms | 116ms | ~11x |
Zoom out, and the ~$38K/month saved is also worth sizing against the company’s total cloud bill. That puts this single migration’s savings at roughly 15-16% of Komodor’s entire infrastructure spend.
By the numbers, this was six services, roughly 110 pull requests, built end to end flag-gated and reversible, from December 2025 to the current rollout push finishing between end of July and early August 2026.
What’s next
After the final accounts have completed migration to ClickHouse, Timestream can be fully decommissioned. Every legacy Timestream dependency has been logged in a running cleanup document throughout the migration, and once the last accounts clear validation, removing them moves straight into the standard sprint cycle.
The team also built a safeguard for that cleanup while the migration was still underway: every pull request tied to this project was required to append its structural changes to an automated changelog, rather than relying on a wiki page to track over 150 PRs’ worth of changes across two languages by hand. That changelog, sitting in git history, becomes the input for an AI-assisted pass during cleanup — locating and pruning every remaining legacy code hook without guessing, and without the regression risk of doing it from memory.
Finishing the rollout is the foundation here, not the ceiling. Being on a general-purpose engine instead of a purpose-built time-series one opens up work that simply wasn’t on the table before:
- Separate compute, shared storage. ClickHouse Cloud lets the team spin up independent clusters over the same underlying storage — for backfills, product analysis, or other dedicated workloads — and scale each to its own need instead of contending for the same resources. It’s the microservice mindset, applied to the data layer.
- Query optimization headroom. The queries running today were largely carried over from Timestream as-is. ClickHouse’s specialized MergeTree engines — AggregatingMergeTree, and the newer CoalescingMergeTree — let the team push aggregation and deduplication down into the storage layer itself, where it pays off the most, instead of handling it in application code.
- General-purpose flexibility. Timestream locked the team into a time-series shape for everything. ClickHouse doesn’t — ad-hoc DML, schema evolution, and joining metadata directly in queries mean the same engine can now handle categories of work that used to require bolting something else on around the database.
- Native RDBMS sync via ClickPipes. Instead of hand-rolled dual-writes and application-level joins, the plan is to sync external relational data into ClickHouse natively and join it directly in-query — retiring a whole category of workaround code that only ever existed to compensate for what the old database couldn’t do.
In retrospect – What we would do differently
The database research, the architectural mapping, and the core implementation were solid from the start — the team stands by all of it. The validation framework is what actually saved the project from shipping silent data mismatches to customers. But if this started over today, the automated validation scripting would be built on day one, not assembled mid-flight, halfway through the validation phase, as the comparison dashboards actually were. Building the harness before you need it, instead of while you’re already debugging under pressure, is the one piece of advice worth carrying into the next migration like this.
One thing that is also on the record, from Nir, Director of Platform Engineering:
“The next easiest thing is to just continue. Sometimes as engineers we need to ask ourselves if we need to go into a mega project, and whether it will be worth it. Replacing infrastructure needs to be done with a lot of thought and planning.”
Where AI actually helped, and where it didn’t replace judgment
Max joined Komodor and this project at essentially the same time — nine months at the company total, roughly five of them embedded full-time in this migration. Coming in new to a system of this scale and complexity, the real hurdle wasn’t the new database; it was building context on the legacy ingestion data flows nobody had to explain to him from scratch, because nobody had time to.
“Without using AI tools to parse the legacy codebase and map out the data paths, building that context would have taken me months longer. The AI workflow was an absolute force multiplier during the validation phase when debugging the deltas.” — Max Dubinin
The specific breakthrough wasn’t a chatbot answering questions — it was automation. Early attempts to debug the Timestream/ClickHouse discrepancies were manual: engineers parsing raw, asynchronous query logs together in a live meeting room, which didn’t work. What did work was writing generation scripts that output live HTML validation reports instead — a visual, shareable artifact where a data mismatch could be isolated in seconds instead of reconstructed from logs by hand. That’s the tooling that became the cost-parity and lineage reports described above.
From the management side, the read was blunt: comparing live customer metrics across two engines down to the single integer, by hand, would have taken weeks the team didn’t have the bandwidth for. The scripting is what made a rollout this careful possible on the timeline it ran on.
“This was a big project that took multiple months to complete. Completely driven by R&D, [it] needed a big change.” — Nir, Director of Platform Engineering
“He joined the company, got thrown straight into the absolute deep end of our metrics architecture, and handled the entire execution beautifully. Despite my constant context changes and late-night debugging calls to track down elusive data anomalies, his execution was outstanding. It was a true pleasure collaborating on this.” — Shai on Max